make preferable
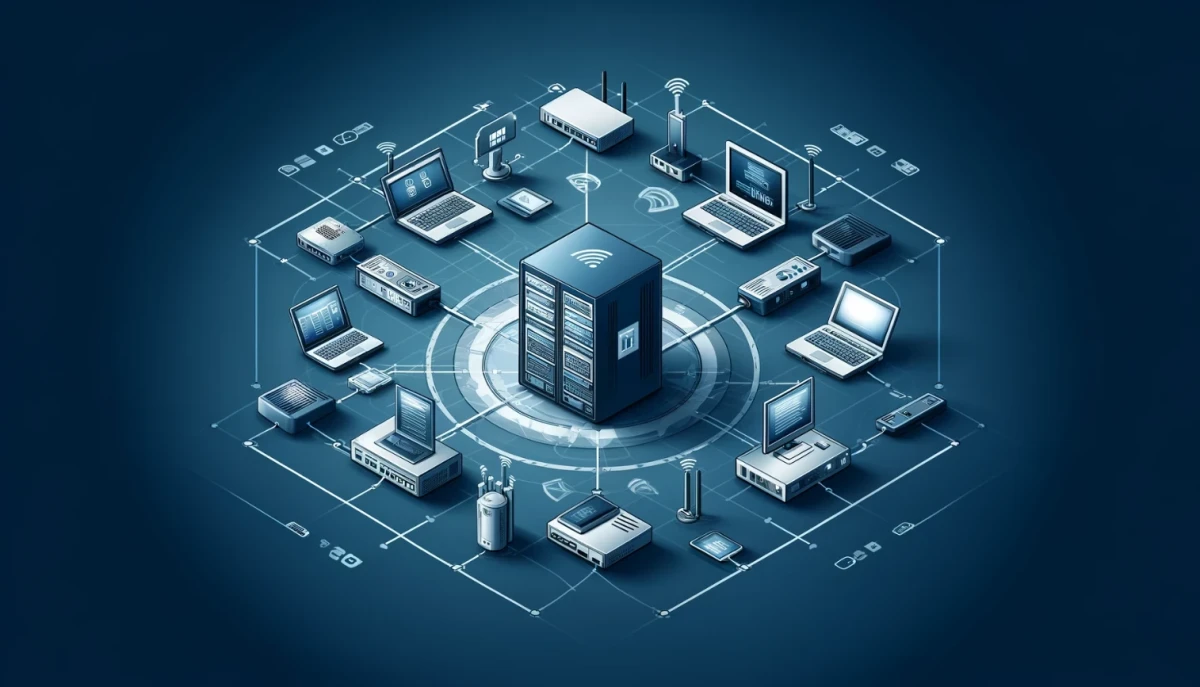
The artificial intelligence industry is gradually shifting its focus from training models in giant data centers to their everyday use — processing requests and generating responses directly where the data is created. This approach is called edge computing, or edge AI. It helps reduce latency and makes it easier to comply with data storage requirements, but at the same time it makes protecting infrastructure from cyberattacks more difficult, Axios reports.
Training gives way to running deployed models
Training AI models requires significant computing resources, so companies build large data centers capable of handling massive computational workloads. But once a model has been trained, it must be used continuously: to analyze information, respond to queries, recognize images, and help make decisions. This process is called inference.
According to a McKinsey forecast, by 2027 inference computing could surpass model training in total workload volume. By 2028, it could overtake both AI training and traditional non-AI computing.
As AI is integrated into corporate processes, more and more computing may move from centralized clouds closer to where the data originates. Instead of sending all information to a remote server, organizations will be able to run models on local servers, specialized devices, and small compute sites.
An earlier Gartner forecast suggested that by 2025, 75% of data created by enterprises would be generated and processed outside traditional data centers and cloud infrastructure. That was an estimate of a future trend, not a confirmed indicator of the actual volume of computing.
Why AI needs to be deployed closer to users
The shift to edge computing is especially important for industries where even a delay of a few moments can affect the outcome. If a system must make decisions in real time, constantly reaching out to a remote data center may be inconvenient or too slow.
There is another reason as well — control over data. Large companies and organizations operating in regulated industries need to comply with requirements governing where information is stored and processed. Local infrastructure helps keep data within a specific country or territory and reduces dependence on external cloud services.
According to Available Infrastructure, nine out of ten executives at large companies are concerned about the consequences of these changes for their business and their own work. As AI becomes part of mission-critical processes, issues of computing speed, data location, and system reliability are turning into strategic priorities.
The more nodes there are, the harder cybersecurity becomes
Distributed architecture has a significant drawback: the more devices and sites involved in data processing, the more potential entry points there are for attackers.
If centralized infrastructure can be protected in a relatively limited number of places, edge computing involves deploying servers and other devices across many offices, cities, and industrial facilities. Every additional node must be monitored, updated, and protected from unauthorized access.
In the 2026 CrowdStrike Global Threat Report, edge devices are described as attractive entry points into infrastructure for cybercriminals.
To protect such systems, Available Infrastructure proposes combining a Zero Trust architecture — in which every access request must be verified — with cryptography resistant to potential attacks using quantum computers. In this case, both data in transit and information stored on devices must be protected.
They are trying to turn distributed infrastructure into a network of secure nodes
Available Infrastructure is developing the SanQtum project — a network of small edge computing nodes designed for deploying AI in cities and other locations where high performance with minimal latency is required.
According to the company, SanQtum nodes are being designed with data sovereignty, fault tolerance, and cybersecurity requirements in mind. They use a Zero Trust architecture and post-quantum protection.
The first deployment phase, Project Qestrel, calls for creating 1,000 sites in 100 U.S. cities, covering more than 30 states. The nodes are expected to be grouped into clusters of three sites to improve network resilience, connected by dedicated fiber-optic lines within regions.
The company says the infrastructure is already operating in several cities, and construction of more than 200 sites is underway. The provided material contains no independent confirmation of the claimed specifications or deployment scale.
The future of AI depends on more than just the size of data centers
Edge computing does not eliminate the need for large model-training centers. Rather, the industry is moving toward a distributed architecture in which massive data centers train AI, while local nodes enable it to operate under specific conditions.
This model could make AI faster and more convenient for enterprises that need to process data on-site. But the broader the network of compute sites becomes, the higher the requirements for infrastructure management, device protection, and compliance with regional rules for handling information.
That is why the next stage of AI development will be determined not only by the number of accelerators and the power of the largest data centers, but also by how reliably companies can deploy trained models beyond the centralized cloud.